

Cross-session memory
Remembering things about a customer
A customer tells your agent they prefer deliveries after 6 PM. When they come back in a new chat, the agent should already know that. Cross-session memory is what your agent carries from one conversation to the next: preferences, constraints, and facts the customer shared. Parlant does not store these itself. Instead it gives you two connection points, one that saves facts after each reply and one that reads them back before the next reply, so you can plug in the memory service you prefer.
- The difference between session memory and cross-session memory
- How a hook saves the exchange after each reply, without delaying it
- How a retriever brings saved facts into the next reply
- A complete example built on mem0, with notes for production
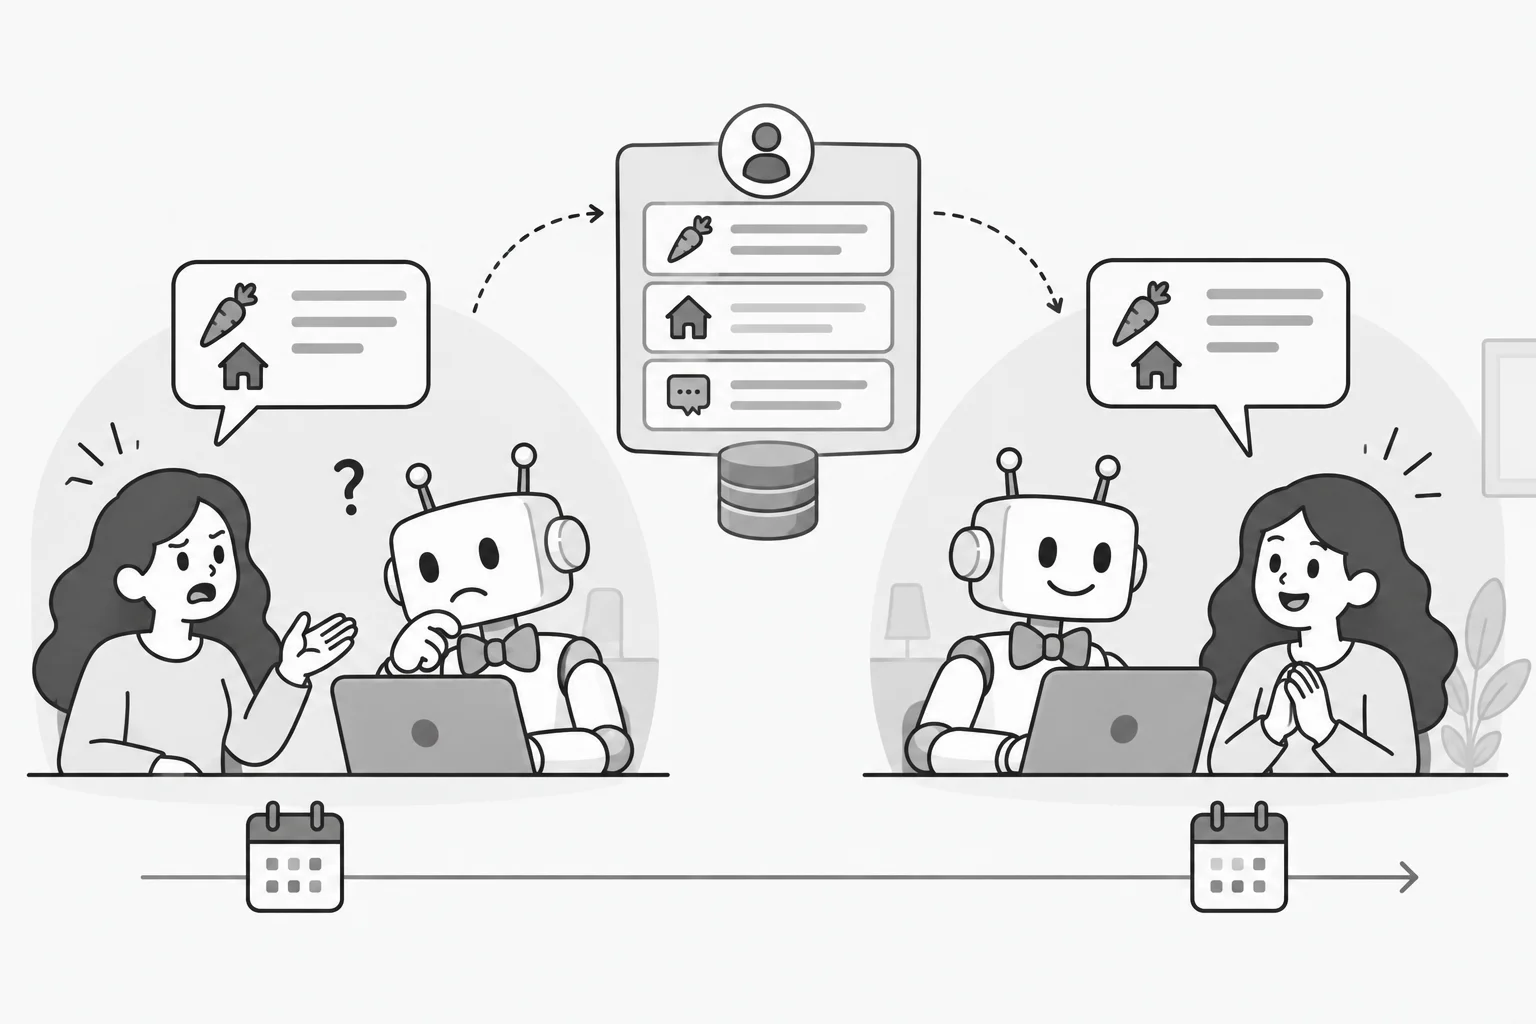
This playbook shows how to save useful facts from one conversation and retrieve them in another.
But first, a note about how memory works in Parlant. There are two kinds.
Session memory is the running conversation: its history and, once it grows long, a summary. Parlant manages that automatically, so you do not need to think about it.
Cross-session memory is what the agent should carry from one conversation to the next, like a preferred delivery window, some communication preferences, or a product the customer showed interest in.
A new session does not automatically include the old session's history. To reuse selected facts about a customer, store them under the customer's ID and retrieve them when they matter. For such memories, Parlant does not ship its own memory store, but it makes it easy to connect the memory store of your choice.
The integration needs two connection points: an engine hook that sends the exchange to the memory layer, and a retriever to read saved facts before a reply.
Saving useful facts from customer messages
Let's start by saving the memories.
We send the latest customer message and the agent's replies to your memory layer of choice, so it can extract facts worth keeping. Each completed exchange is sent once, without resending earlier messages.
We use a compass engine hook to do that. A hook is a callback that runs at a particular point on every conversation turn. Use the on_messages_emitted hook to write after the reply has been delivered, so extraction does not delay it.
The hook's payload is the list of messages the agent delivered this turn, in order. This includes any message sent before a tool call, such as "Let me check that," as well as the final reply.
Here, memory_store is a placeholder for some memory service that your application uses (e.g. mem0). We give it the customer ID to identify whose memories to save, and the session ID to keep each conversation's extraction context separate. The mem0 section below shows how this works and how to select useful facts.
from collections.abc import Sequence


async def save_memories(
    ctx: p.EngineContext, payload: Sequence[str], exc: Exception | None,
) -> p.CompassHookResult:
    # In this hook, `payload` contains the assistant's messages for this turn

    if msg := p.Session.current.interaction.last_customer_message:
        messages = [
            {"role": "user", "content": msg.content},
            *({"role": "assistant", "content": text} for text in payload),
        ]
        try:
            await memory_store.add(
                messages,
                customer_id=p.Customer.current.id,
                session_id=p.Session.current.id,
            )
        except Exception as error:
            p.Server.current.logger.warning(f"Memory write failed: {error}")
    return p.CompassHookResult.CALL_NEXT


async def setup_hooks(container: p.Container) -> None:
    container[p.CompassHooks].on_messages_emitted.append(save_memories)

async def main() -> None:
    async with p.Server(initialize_container=setup_hooks):
        ...
Pass initialize_container to p.Server when starting your project, as shown above. This registers the hook at startup.
A short answer such as "After six" needs the question that came before it. This example relies on the memory service keeping recent exchanges as context for later writes. mem0 does this automatically; check that behavior if you use another service.
Retrieving relevant memories before a reply
Before answering a returning customer, we search their saved facts using the new message.
A retriever lets us supply those facts to our agent. It runs during a turn's preparation, in parallel with rule matching (so it adds no visible latency), and whatever it returns is injected into the prompt for this reply.
async def recall_memories(_: p.RetrieverContext) -> p.RetrieverResult | None:
    if msg := p.Session.current.interaction.last_customer_message:
        if facts := await memory_store.search(msg.content, customer_id=p.Customer.current.id):
            return p.RetrieverResult(
                data=(
                    "Memories about this customer (use naturally, only if/when relevant):\n" +
                    "\n".join(facts)
                )
            )   # retriever data goes into the prompt

    return None   # no relevant memories: inject nothing into the prompt

...

# This is how you attach your retriever to the agent
await agent.attach_retriever(recall_memories)
Return None when nothing is relevant, so an empty section never reaches the model. Retrieved context lives for this reply only, so it does not accumulate tokens into the next turns. Retrieving knowledge covers retrievers in general.
That is the whole pattern. These functions work together: save_memories saves facts about a customer, and recall_memories retrieves them.
Putting it together with mem0
Here is how to replace the placeholder memory_store with mem0.
For this delivery-support example, we use custom instructions to focus on ongoing delivery preferences, access constraints, and contact preferences, and also show which messages should produce no memory.
mem0 keeps the last messages for each combination of identifiers as context for extracting new memories. Using Parlant's session ID as run_id keeps separate conversations from sharing that buffer.
We save memories with both user_id and run_id, but search with only user_id to find memories across sessions (since adding run_id to the search would limit recall to that session).
During extraction, mem0 also limits the existing memories it consults to the supplied identifiers; see its extraction implementation.
import asyncio
import os
from collections.abc import Sequence

import parlant.sdk as p
from mem0 import AsyncMemory


MEMORY_INSTRUCTIONS = """
Extract ongoing delivery preferences, delivery access constraints, and preferred
contact methods that the customer states or confirms in their latest message.
Use earlier messages only to understand that message. Do not extract earlier
facts again merely because they appear in the context.
Use assistant messages to interpret the customer's answer, not as facts about
the customer. Only keep an assistant's suggestion if the customer confirms it.
Skip greetings, casual chatter, hypotheticals, and requests for just one order.
If the meaning is unclear from the supplied messages, do not guess.

Input:
assistant: What delivery time usually works for you?
user: After 6 PM.
Remember: Customer prefers deliveries after 6 PM.

Input:
user: Please text me instead of calling about deliveries from now on.
Remember: Customer prefers text updates about deliveries.

Input:
assistant: Would morning delivery work for you?
user: I'm not sure.
Nothing to remember.

Input:
user: For today's order only, please deliver after 6 PM. Thanks!
Nothing to remember.

Input:
user: Hi, thanks for your help!
Nothing to remember.
"""


async def main() -> None:
    memory_store = AsyncMemory.from_config({
        "llm": {"provider": "openai", "config": {"model": os.environ["MEMORY_LLM_MODEL"]}},
        "embedder": {"provider": "openai", "config": {"model": "text-embedding-3-small"}},
        "custom_instructions": MEMORY_INSTRUCTIONS,
    })

    async def save_memories(
        ctx: p.EngineContext, payload: Sequence[str], exc: Exception | None,
    ) -> p.CompassHookResult:
        if msg := p.Session.current.interaction.last_customer_message:
            messages = [
                {"role": "user", "content": msg.content},
                *({"role": "assistant", "content": text} for text in payload),
            ]
            try:
                await memory_store.add(
                    messages,
                    user_id=p.Customer.current.id,
                    run_id=p.Session.current.id,
                )
            except Exception as error:
                p.Server.current.logger.warning(f"Memory write failed: {error}")
        return p.CompassHookResult.CALL_NEXT

    async def recall_memories(_: p.RetrieverContext) -> p.RetrieverResult | None:
        if msg := p.Session.current.interaction.last_customer_message:
            try:
                result = await memory_store.search(
                    msg.content, filters={"user_id": p.Customer.current.id},
                )
                facts = [item["memory"] for item in result["results"]]
            except Exception as error:
                p.Server.current.logger.warning(f"Memory lookup failed: {error}")
                return None

            if facts:
                return p.RetrieverResult(
                    data=(
                        "Memories about this customer (use naturally, only if/when relevant):\n" +
                        "\n".join(facts)
                    )
                )
        return None

    async def setup_hooks(container: p.Container) -> None:
        container[p.CompassHooks].on_messages_emitted.append(save_memories)

    async with p.Server(initialize_container=setup_hooks) as server:
        agent = await server.create_agent(
            id="support",
            name="Support",
            instructions="You are a helpful assistant. Use what you know about the customer.",
        )

        await server.create_customer(name="Alex", id="crm-42")
        await agent.attach_retriever(recall_memories)


if __name__ == "__main__":
    asyncio.run(main())
Notes for production
- Use the same customer ID across sessions. Both callbacks use
p.Customer.current.id, so a new session can find the same customer's saved facts. Hooks run for every agent on the server. If you add other agents, you can usep.Agent.current.idto tell them apart. mem0 also supports filtering byagent_id. - Memory is not the customer record. Facts your systems own, such as the plan or the address, belong in variables and metadata, set from your backend; see customer variables. Memory is for capturing context from the conversation itself, and it is more volatile by nature.
- Use a different trigger when needed. Instead of saving memories on every emitted message, you can use a more specific trigger. An observation combined with an
on_matchedhandler lets you select which situations should send data to the memory layer, without the latency of a tool call.